Machine Learning Revision (Notes)
Lecture-by-lecture revision notes for the DA5400 machine learning course: clustering, estimation and EM, and supervised learning (regression). Each page summarises one lecture with interactive demos and links to its video.
Source: Arun Rajkumar · DA5400. These are my personal, unofficial notes; explanations and extensions are my own, so check the lectures for the definitive treatment. Maths and charts load from public CDNs.
Clustering
- L13Introduction to clustering: Partitioning data, the K-means objective, and why exhaustive search is NP-hard video
- L14K-means (Lloyd's algorithm): The two-step algorithm and the open questions it raises video
- L15Convergence of K-means: Why the objective strictly decreases and the algorithm must stop video
- L16Nature of K-means clusters: Perpendicular bisectors, Voronoi regions, and kernel K-means video
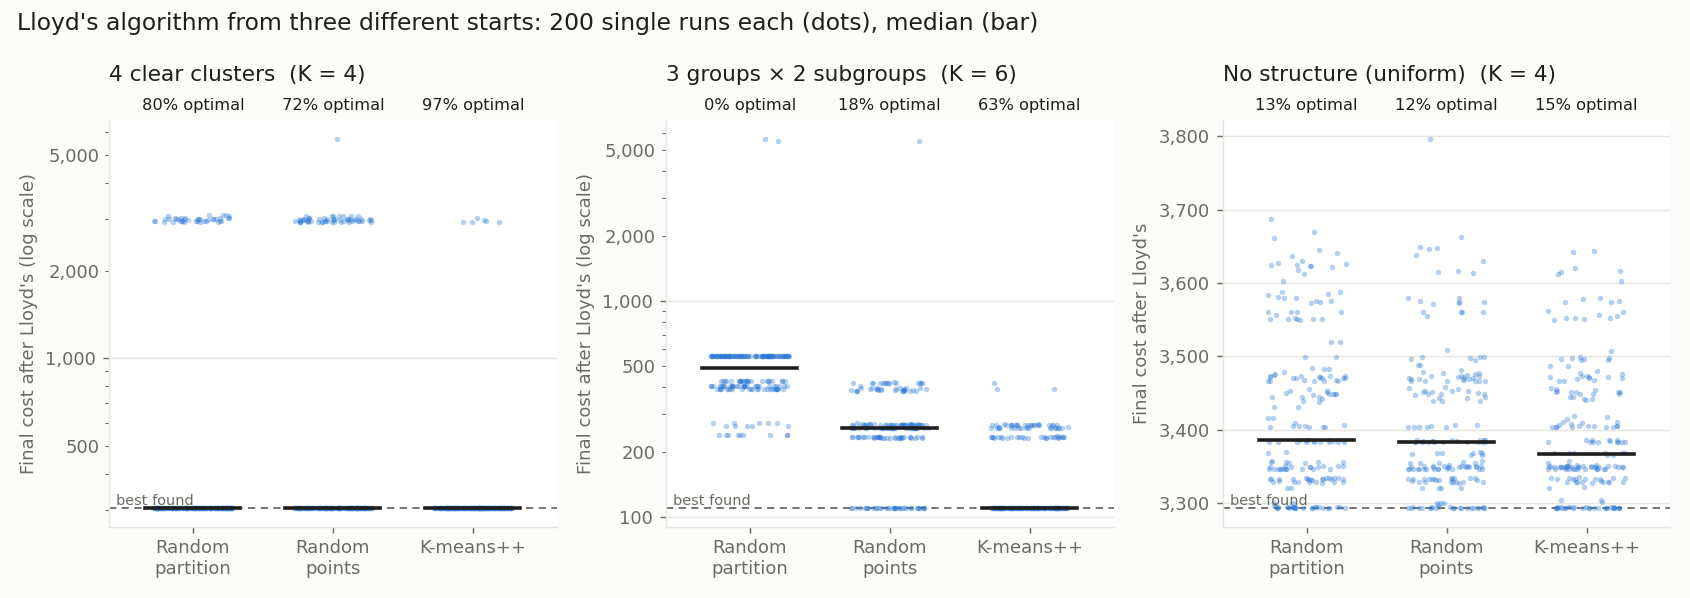
- L17Initialising K-means: Random restarts and K-means++ video
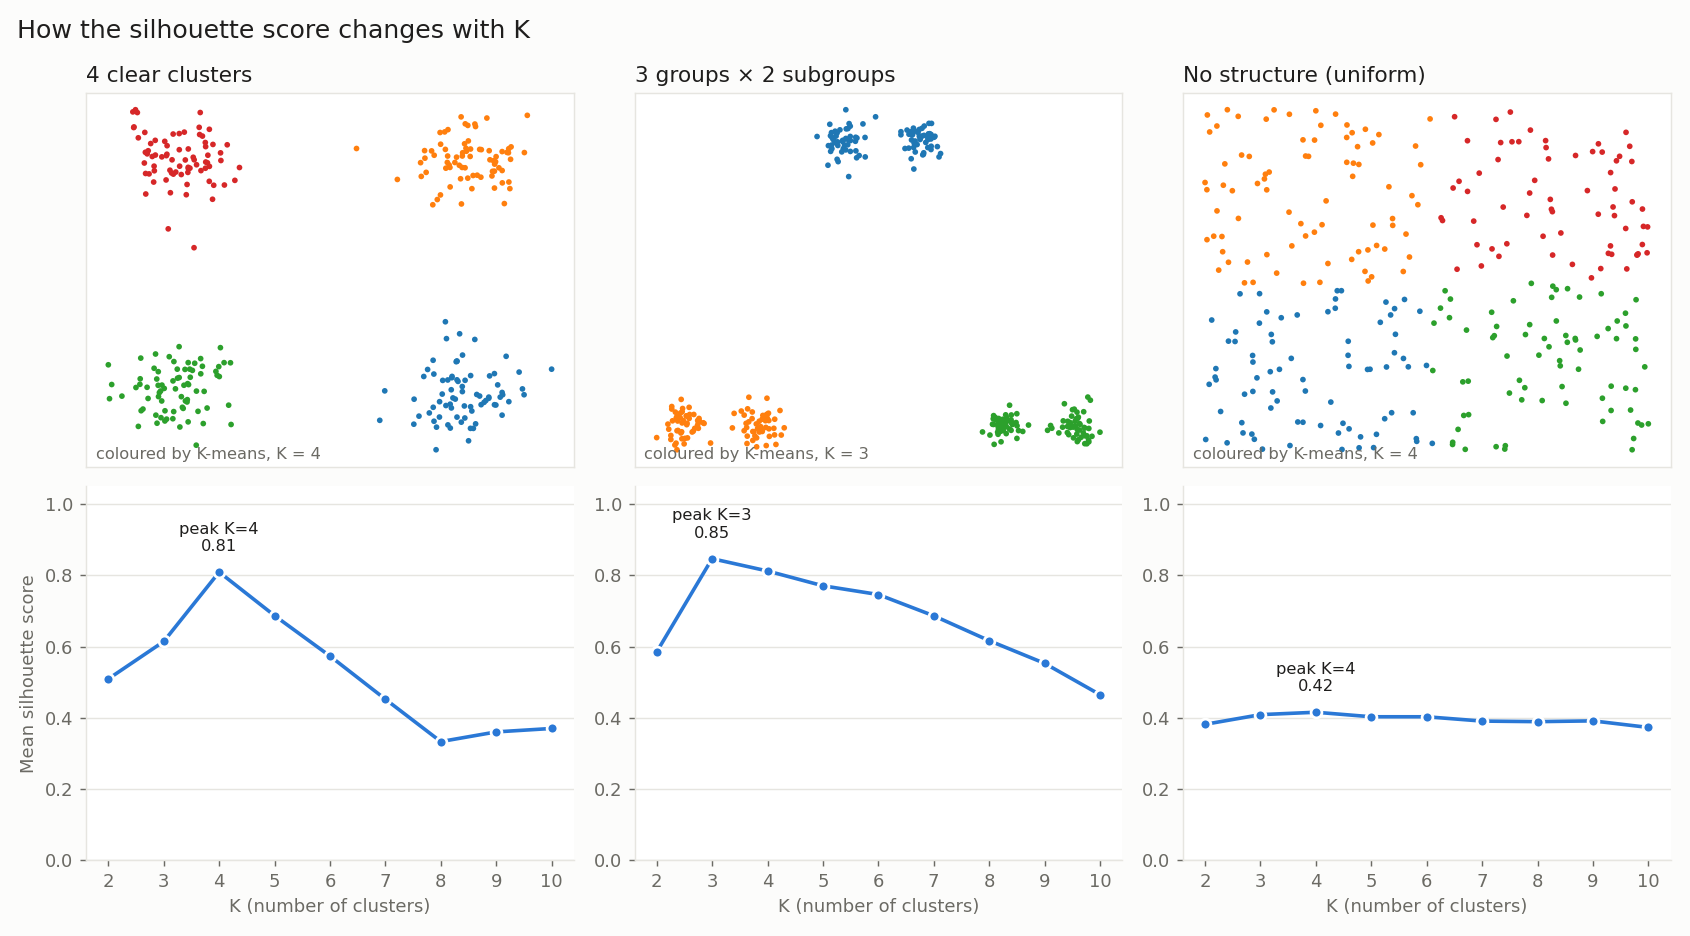
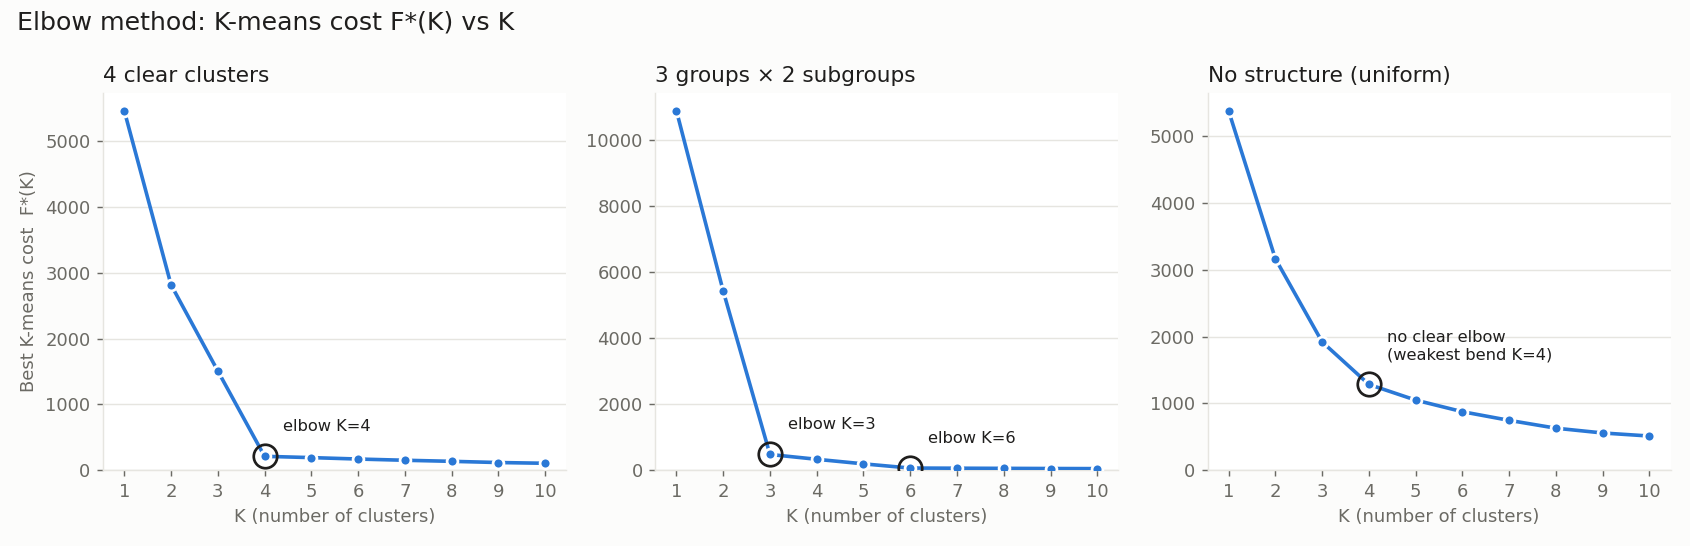
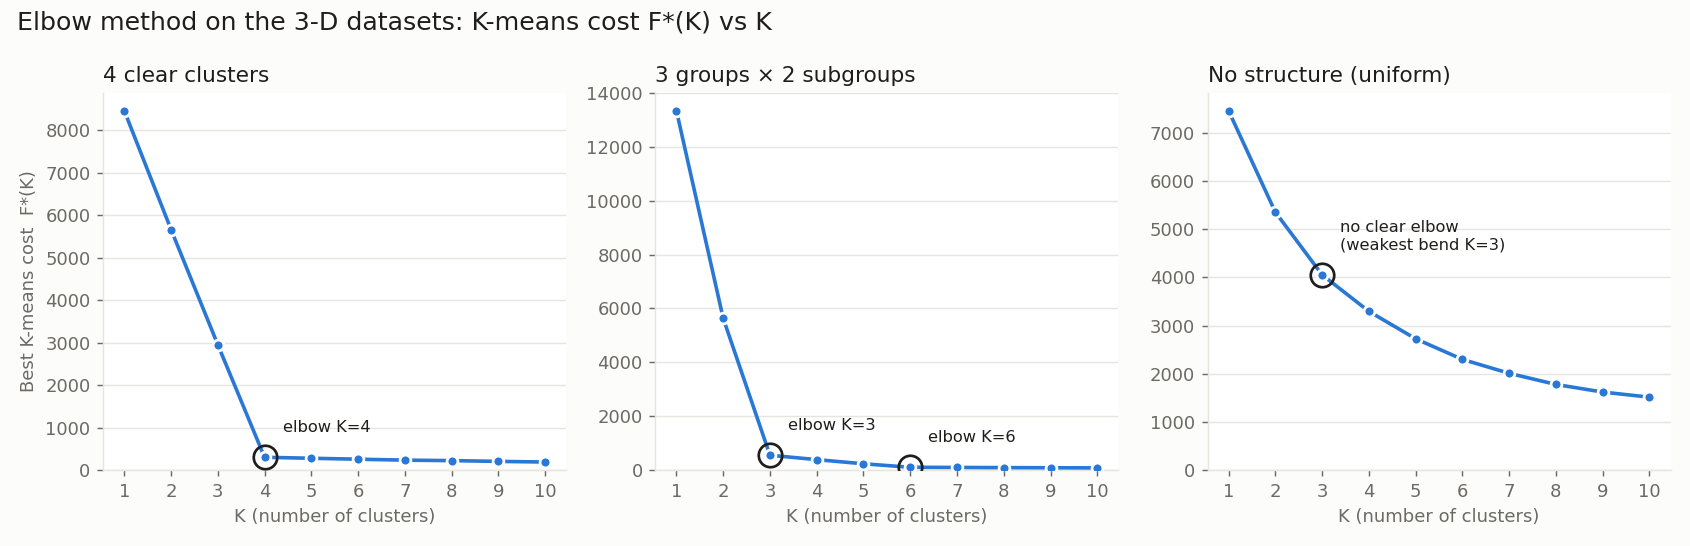
- L18Choosing K: Objective + penalty, AIC/BIC, elbow and silhouette video
Estimation
- L19Introduction to estimation: Probabilistic models, unknown parameters, and the i.i.d. assumption video
- L20Maximum likelihood: Fisher's principle, log-likelihood, and densities for continuous data video
- L21Bayesian estimation: Priors, posteriors, the Beta–Bernoulli update, MAP video
- L22Gaussian mixture models: The two-step generative story and latent variables video
- L23Likelihood of a GMM: Why a sum inside the log blocks a closed-form answer video
- L24Convexity and Jensen's inequality: The chord test, and why log being concave helps video
- L25Estimating GMM parameters: A Jensen lower bound that is easy to maximise in two halves video
- L26The EM algorithm: E and M steps, soft K-means, and local maxima video
Supervised learning: regression
- L27Supervised learning: Labels, and binary vs multi-class vs regression video
- L28Linear regression: Squared error, overfitting, and restricting to linear functions video
- L29Solving linear regression: Normal equations, w* = (XXᵀ)⁺Xy, and the pseudo-inverse video
- L30Regression as projection: Projecting the labels onto the feature subspace video
- L31Gradient descent and SGD: Avoiding the matrix inverse, and mini-batches for huge n video
- L32Kernel regression: α = K⁻¹y and non-linear fits with kernels video
- L33Probabilistic view of regression: Gaussian noise ⇔ squared error video
- L34Goodness of the ML estimator: E‖ŵ − w‖² = σ² tr((XXᵀ)⁻¹) video
- L35A better estimator and cross-validation: (XXᵀ + λI)⁻¹Xy and K-fold CV video